Rakesh Sawant
Senior Backend & AI Engineer
Agents, inference, fine-tuning and retrieval, and the backend that keeps them working in production.
Most AI systems are impressive in demos. Fewer survive messy data, shifting requirements and real traffic. I build the ones that survive.
Inside the model
One sentence through GPT-2, one step at a time.
Watch a sentence move through GPT-2, one step at a time, in plain words. The formulas are one click away.
Real GPT-2 small (124M) weights and activations, precomputed with Hugging Face transformers. Not running live.
-
Tokenize
The computer can't read English, so the sentence is first cut into pieces it does understand. Common words become one piece each; rarer words get split into a few. It's choosing from a fixed list of 50,257 pieces it memorized while it was being trained.
In the drawing: the sentence is one bar, cut into six pieces.
Show the formula
Text becomes tokens. GPT-2 splits it using a learned vocabulary of 50,257 pieces, so a word can be one token or several.
this splitting method is called byte-pair encoding (BPE)
-
Embed
Each piece is swapped for a long list of 768 numbers, its coordinates in a huge space where words with similar meanings end up sitting near each other. Only the first 16 of those numbers are drawn, the rest work the same way.
In the drawing: a row of 16 pegs rises behind each piece, one peg per number. Tall pegs are large numbers; pegs hanging below are negative.
Show the formula
Each token id looks up a learned vector of 768 numbers. Shown here: the first 16.
this lookup table has 50,257 rows, one per possible piece
-
Position
The model looks at the whole sentence in one go, so on its own it has no idea which word came first. A second set of numbers marking "1st word", "2nd word" and so on gets added on top, so order is not lost.
In the drawing: dashed pegs, the position numbers, drop onto each row and merge into it.
Show the formula
The model has no built-in sense of order, so a learned position vector is added to every token.
-
Attend
Now the model looks at the word it's about to guess after, and glances back over every word said so far to weigh how much each one matters, the same way you might reread the start of a sentence to remember what it was about. Older GPT-2 models have a well-known habit of leaning heavily on the very first word, which is the tall stack you see here.
In the drawing: arcs reach back from the last word, "in". Each stack is how much attention it pays that word.
Show the formula
Take the last word, the one that has to predict what comes next. It looks back at every word so far and decides how much each one matters. The height of each stack is its share of that attention (layer 5, averaged over 12 heads).
M stops the model from peeking at words that come later
-
Heads
The model doesn't just glance back once, it does it twelve times at once, in twelve separate ways, called heads. One head might track grammar, another might track which name a pronoun refers to, and so on.
In the drawing: twelve small plates appear, one per head. The stacks on each plate show where the last word looks in that head.
Show the formula
Twelve heads attend in parallel, each learning its own pattern.
-
Layers
That whole glance-back-and-think step is called a layer, and the model doesn't do it just once. It repeats the same layer twelve times in a row, each pass refining its understanding of the sentence a little further before handing it to the next layer.
In the drawing: twelve layers stacked into a tower. Each word climbs its own rod, the residual stream, and the bright layer is the one it is passing through.
Show the formula
Attention and a feed-forward network, each with a residual connection and LayerNorm, form one block. GPT-2 small stacks twelve.
each layer keeps a copy of its input and adds its own changes on top, so nothing gets lost on the way through
-
Softmax
After passing through all twelve layers, the model is left with one final set of numbers describing everything it now understands about the sentence. It compares that against all 50,257 possible pieces and turns the result into a probability for each one: how likely it is to come next.
In the drawing: a skyline of the most likely next pieces sits on top. Each column's height is its probability, and the low ledge stands for the other 50,247.
Show the formula
The final vector at the last position is scored against the whole vocabulary and turned into probabilities.
it reuses the same lookup table from the Embed step, in reverse
-
Sample
The single most likely next piece is picked, stuck onto the end of the sentence, and the entire process runs again from the start on this slightly longer sentence. Do that over and over, one piece at a time, and that is how the model writes.
In the drawing: the tallest column wins and drops into the sentence as a new piece with a dotted lid. Then it happens again: their, ability, to, predict.
Show the formula
Take the most likely token, append it, and run everything again. That loop is text generation.
always picking the single most likely piece is called greedy decoding
Selected work
-
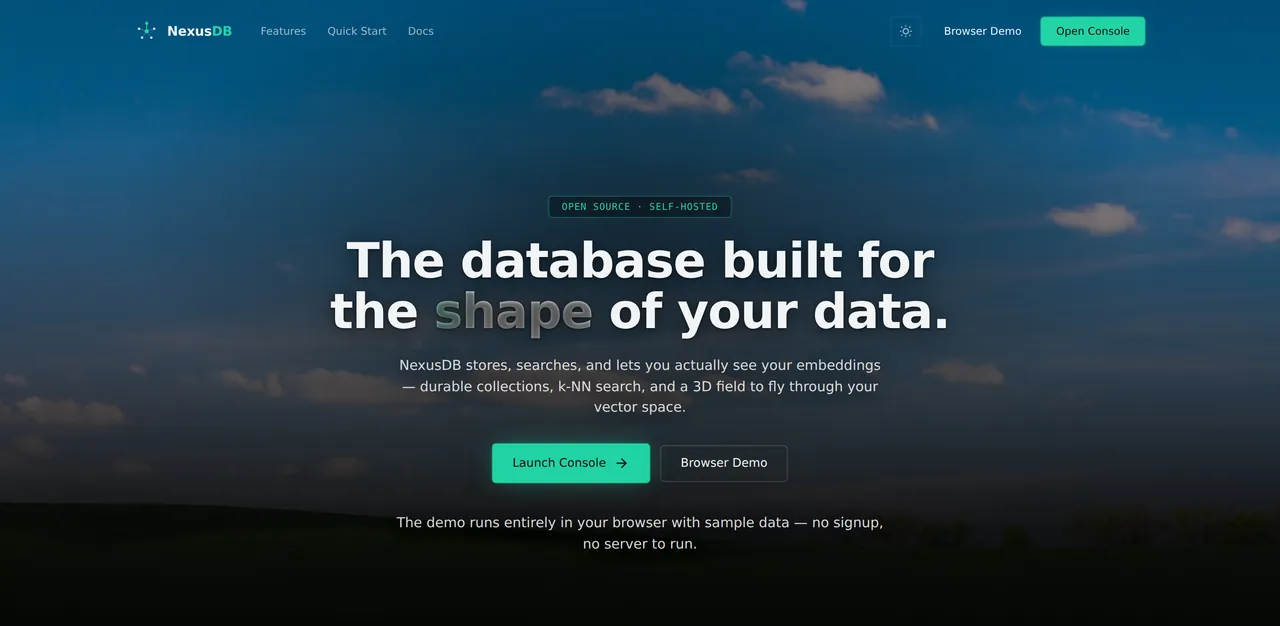
- Problem
- Most build-your-own vector database projects stop at brute-force cosine similarity over a list. That demos well and says nothing about what an approximate index costs you, or how the thing behaves once it is running.
- Approach
- An HNSW index written from first principles, next to an exact flat index, behind one collection API, with metadata filtering pushed down into the search path. Writes go to SQLite in WAL mode, so a hard kill does not corrupt it. FastAPI in front with auth, rate limiting, structured logs, Prometheus metrics and tracing, and a 3D view of the embedding space in the browser.
- The hard part
- Reporting the numbers honestly. At 100,000 vectors, HNSW does about 25x fewer distance computations than brute force, yet pure-Python hops cost it the win: 96% recall needs a search setting about 12x slower than the exact index. The write-up reports that instead of the flattering setting.
- Stack
- Python · FastAPI · NumPy · SQLite · React · Three.js · Docker
-
- Problem
- Agents fail like distributed systems. A tool times out, a step retries, and the next step builds on an empty result as if nothing happened.
- Approach
- ReAct when the next step depends on what the last one found. ReWOO when the plan can be fixed up front, so tools run in parallel and the model is called twice instead of once per step. Either way, state is explicit: checkpoints, idempotent tool calls, and a way to resume.
- The hard part
- Making failure visible to the agent. An empty result and a failed call look the same unless you design them not to.
ReAct
ReWOO
Same question, same three tools. ReAct asks the model before every tool call and once more to answer: 4 calls, one after another. ReWOO plans once, runs the tools in parallel, and solves once: 2 calls. A dot on a model's lid is one call. Related: The stateful agent problem · Multi-agent orchestration
-
- Problem
- A model that answers well in a notebook still has to answer thousands of requests without the latency tail or the GPU bill getting away from you.
- Approach
- Serving with request batching and KV-cache reuse, quantized weights where quality holds, and routing so short requests do not queue behind long generations.
- The hard part
- Every lever trades against another. Bigger batches raise throughput and tail latency together.
-
- Problem
- Some behaviour cannot be prompted reliably: a strict output format, a domain vocabulary, a refusal boundary.
- Approach
- Parameter-efficient fine-tuning (LoRA, QLoRA) with supervised fine-tuning and preference tuning (DPO) on open models, fed by a synthetic data pipeline that generates, filters and deduplicates examples before any GPU time is spent.
- The hard part
- The dataset, not the training run. Synthetic data inherits the blind spots of the model that generated it unless you filter for them.
-
- Problem
- RAG demos retrieve the right chunk for the question they were built around. Real users ask the other questions.
- Approach
- Hybrid retrieval, lexical and semantic, with a reranker on top, and knowledge graphs where relationships matter more than similarity. Evaluation runs like tests: LLM-as-judge scoring, regression sets and guardrails before anything ships.
- The hard part
- Measuring it. Without an evaluation set, every retrieval change is a guess.
-
- Problem
- An AI feature is a backend feature with an unpredictable, expensive dependency in the middle.
- Approach
- Deploying and monitoring models in production, a gateway in front of them, rate limiting by token budget instead of request count, and async pipelines so storage never waits on inference.
- The hard part
- Cost control that does not punish normal users when one user sends a very large request.
Related: The token budget · The async AI processing pipeline
Experience
-
2025–now
Strategy formerly MicroStrategy
AI/ML Engineer
AI features inside an enterprise BI platform: retrieval over business data, model orchestration, and the backend services and APIs that run them at scale.
-
2023–2025
Cognizant
AI Engineer
Hybrid RAG, synthetic data pipelines and knowledge graphs.
-
2022–2023
Cognizant
ML Engineer
Semantic search and the ML pipelines behind it.
-
2017–2021
SPPU
B.E. Electronics & Telecommunication
Notes
- Multi-Agent Orchestration Wiring three LLM agents together isn't an AI problem, it's a distributed systems problem. Orchestration vs. choreography, agent-level circuit breakers, and why shared state between agents will bite you exactly the way it bit microservices a decade ago.
- The Stateful Agent Problem Multi-step LLM agents aren't an AI problem. They're a distributed systems problem wearing an AI costume. State consistency, idempotency, saga patterns, checkpoint-and-replay: every hard lesson from the microservices era is showing up again, and most agent frameworks are pretending it isn't.
- The Token Budget Your AI feature has 10,000 users and a 90K TPM ceiling from OpenAI. One power-user can bankrupt your entire API budget in under a minute. Here's how to build token-aware rate limiting that actually holds up.
- The Async AI Processing Pipeline Why treating ML pipelines like HTTP requests will destroy your production system, and how to build AI infrastructure that actually scales.
Contact
Have a system that needs to hold up in production? Write to me.
- GitHub
- Résumé (PDF)
- Pune, India
Typeset in Absans (the triple-t is Collletttivo’s, not a typo) with a side of JetBrains Mono. Glued together with Astro, set in motion with GSAP, with zero hallucinations, as far as I know.